Products & Models · Nov 1, 2026
Pinecone releases its search engine as a Postgres extension, but the numbers are its own
pg_pinecone is licensed under Apache 2.0. It runs RAG retrieval inside an existing Postgres database without a Pinecone account, and users can move to Pinecone's cloud as they scale. Pinecone measured both the claim that its index is about 1/30 the size of pgvector's and the speed figures itself
Rie Suzuki · Technology Editor
Key points
- Pinecone has turned its search engine into a Postgres extension, pg_pinecone, and released it under Apache 2.0. Users can run RAG retrieval inside the Postgres they already use, without a Pinecone account
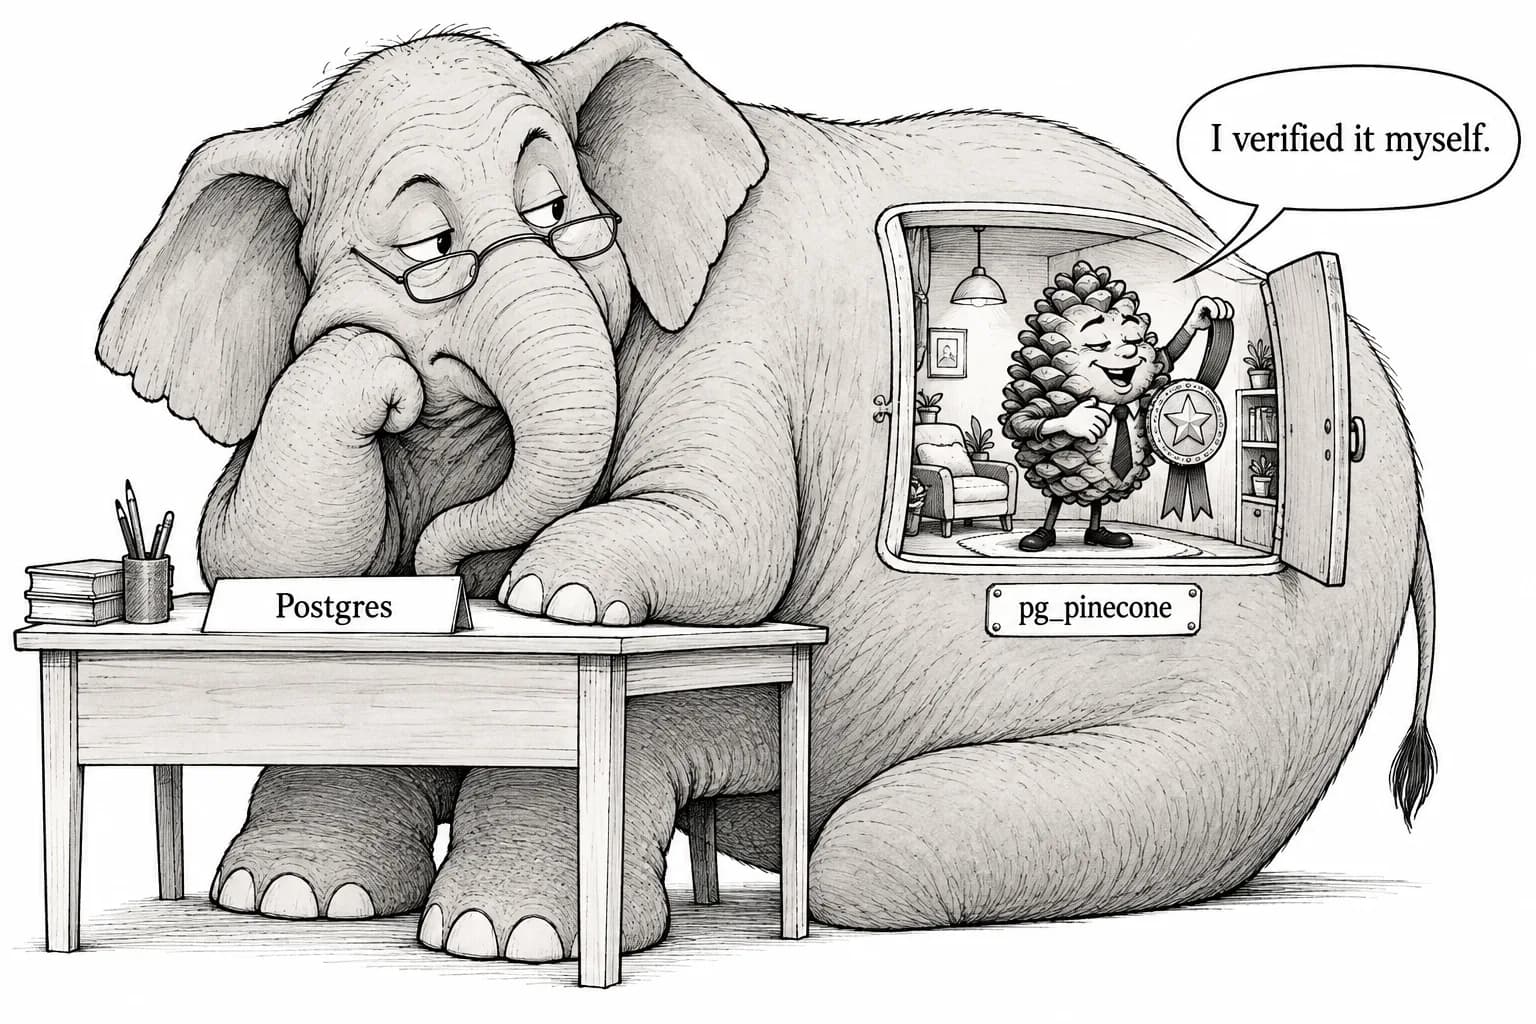
- Pinecone has also given users a way to start inside Postgres and move to Pinecone's cloud as they scale. The free entry point is wide open, and the exit leads to the company's own paid service
- Pinecone measured all of its figures itself, including an index about 1/30 the size of pgvector's and faster search. No third party has yet run a comparison that controls for the data used, the recall and the pgvector configuration
Vector database company Pinecone has released its search engine as a Postgres extension called pg_pinecone. It is licensed under Apache 2.0. Users can run RAG retrieval inside a Postgres database they already have running, without creating a Pinecone account. As their data grows, they can move to Pinecone's cloud. Pinecone says the index is about 1/30 the size of pgvector's and that search is faster. However, Pinecone made all of these comparisons itself.
This article is based on Pinecone's announcement blog post (Introducing pg_pinecone), the product documentation (pg_pinecone overview) and Pinecone's newsroom. All three are primary sources. European IT publication Techzine has also reported on the release.
What it released: its own search engine, inside Postgres
pg_pinecone takes the search engine Pinecone has sold as a cloud service and packages it as a Postgres extension. For users, this means they can run vector search on their existing Postgres tables without standing up a new database or signing up for an outside service.
Until now, the open-source pgvector has been the de facto standard for vector search in Postgres. Pinecone is now bringing its own search technology into the same place. Because the extension is under Apache 2.0, the license lets anyone modify it or build it into their own products.
RAG, the step that retrieves search results and passes them to a model, is now expected in almost every application. There is strong demand to keep that retrieval in the same Postgres database as the application's data. Splitting data across two places means extra work keeping the copies in sync and managing permissions twice. pg_pinecone is aimed squarely at that demand.
The strategy: a free entry point, with the exit leading to Pinecone's cloud
The most important part of the announcement is that users who start inside Postgres can move to Pinecone's cloud once they reach a larger scale.
What follows is the author's analysis, but the strategy is clear. Dedicated vector databases have been under pressure from the argument that "adding pgvector to Postgres is enough." Pinecone has stopped treating Postgres as a rival and has put its technology inside it instead. While a deployment is small, it is free and runs where users already work. When it grows and running the index becomes a burden, Pinecone's own paid cloud is the first destination they see. Pinecone is using open source as an entry point to its own business.
Users no longer have to decide up front whether to sign up with Pinecone. On the other hand, the more closely pg_pinecone's indexes and query syntax match Pinecone's cloud, the easier it becomes to move there, and the harder it becomes, by comparison, to switch to anything else. Users keep the Apache 2.0 code, so they are not locked in. Still, it is worth knowing that the easy destination is a single company's service.
All the numbers are Pinecone's own measurements
Pinecone says pg_pinecone's index is about 1/30 the size of pgvector's and that search is faster. A smaller index fits more vectors into the same amount of memory, so users would not need bigger Postgres servers. If the figures hold up, the benefit is substantial.
However, Pinecone ran all of these comparisons itself. At the time of the announcement, no third party appears to have published results measured under the same conditions. Vector search benchmarks can produce very different answers depending on how they are set up. Users should check at least the following points against their own data.
Conditions to check
The first is whether the comparison held recall constant. Recall measures how many of the truly nearest results a search finds. Making an index smaller or a search faster is not hard if recall is allowed to drop slightly. Speed and size figures mean little unless recall is reported alongside them.
The second is how pgvector was configured. pgvector also offers different index types and tuning parameters, and these change both size and speed. The "1/30" figure carries different weight depending on whether Pinecone compared against pgvector's best configuration or left it on default settings.
The third is the size and type of the data used, how long the index takes to build, and how it behaves as data is added and deleted. In production RAG systems, documents change every day. What matters is not only search speed but also how well the index holds up while writes keep coming in.
It is not unusual for companies that publish benchmarks to choose conditions that favor themselves. That is not dishonest in itself, but the numbers should be read with the caveat "according to Pinecone's measurements."
What it means for users
Until now, there were two paths: pgvector for vector search in Postgres, or a company like Pinecone for a dedicated service. pg_pinecone opens a third path between them. Users can keep their data in Postgres and still use search technology built by a dedicated vector search company.
Because the extension is released under Apache 2.0, anyone can read the code and test it with their own benchmarks. Users and independent testers will now decide whether Pinecone's numbers hold up. For now, three things can be said. Users can try the search engine inside an existing Postgres database without an account. A path to Pinecone's cloud is open as they grow. And the claim that it is smaller and faster than pgvector is, so far, Pinecone's own.
Editorial cartoon