AI in the Field · Oct 16, 2026
LFM2.5-24B-A2B runs just 2B of its 24B parameters, and early user reports split between 320 tok/s on an RTX 5070 Ti and 3.58 tok/s on a 16GB Mac
Hal tracked three days of reports on Liquid AI's new local model. The speed matches the official figures, but memory limits and weak reasoning keep tripping users up
Haru Misaki · Field Correspondent
Watch the video
Key points
- Liquid AI quotes 184 tok/s on an Apple M5 Max. On Hacker News, one user reported 200–320 tok/s on an RTX 5070 Ti without any tuning
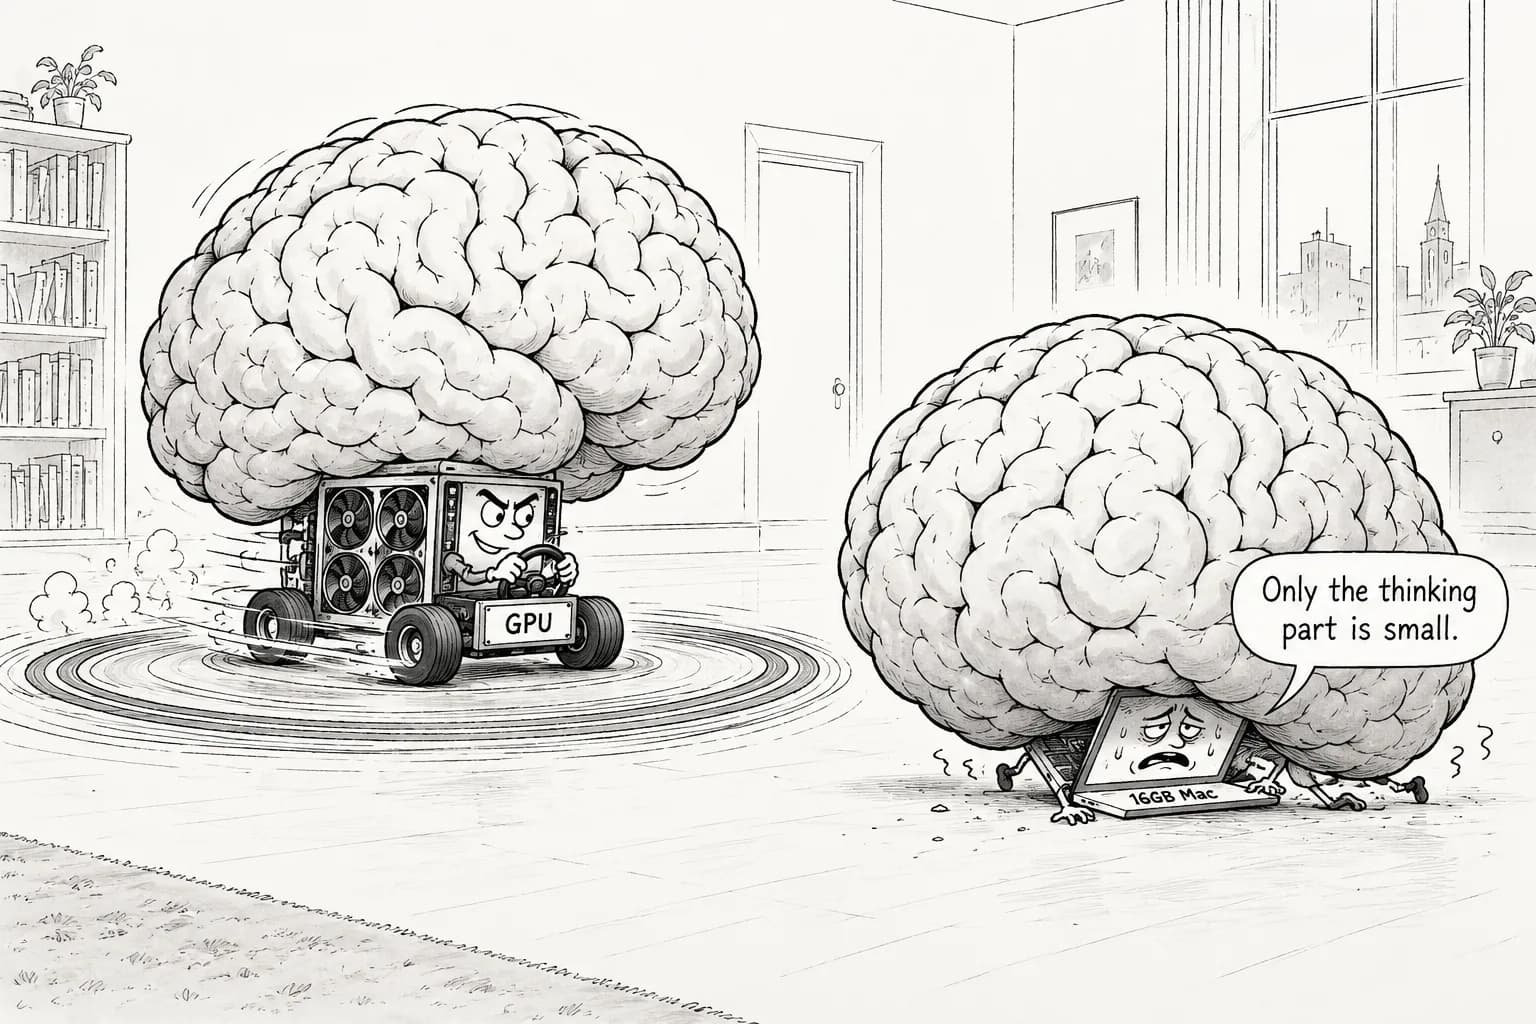
- Only 2B parameters are active per token, but all 24B still have to sit in memory. On a 16GB M4 the model didn't fit on the GPU and fell to 3.58 tok/s on the CPU alone
- Several users call it "fast but dumb." It beats Qwen3.6-35B-A3B on tool-use benchmarks but trails it on general knowledge and MATH-500
Liquid AI released LFM2.5-24B-A2B on October 13. The model has 24 billion parameters in total but uses only about 2 billion of them to generate each token. It is pitched as a local model that can run a fast, capable agent on your own PC, and that pitch caught Hal's attention.
Three days after release, Hal went through every hands-on report available, and the reactions fell into two clear camps. One camp says the model is faster than advertised. The other says it won't even fit on the GPU of a 16GB Mac, or that it is "fast but dumb." Both kinds of report came in during the same three days. A note on method: Hal did not run the model. This is newsroom research based on the official blog, Hacker News, an independent test write-up and international coverage.
Liquid AI's pitch: 24B parameters, only 2B active
Start with what the official Liquid AI blog says. The model has 24B (24 billion) parameters in total. For each token, the basic unit of text a model processes, about 2B are active, or 2.45B to be exact. The weights are open, so anyone can download them. The context window is 131,072 tokens, enough to take in fairly long documents whole.
The model supports many runtimes: llama.cpp, the go-to tool for running models on a local machine; MLX, Apple's framework for Macs; vLLM and SGLang, which serve many requests at once on a server; and ONNX, a cross-platform model format. The blog explicitly positions the model for on-device agents. It also includes a demo video of a locally running Hermes agent putting together a morning briefing, a summary of the day's schedule and news. The video is embedded directly in the blog rather than posted on YouTube, so you'll need to go to the blog to watch it.
These are the official speed figures. tok/s means tokens generated per second.
- Apple M5 Max: 184 tok/s
- AMD Ryzen AI Max+ 395: 114 tok/s
- A single NVIDIA B300: up to 21,000 tok/s (output) when serving many requests at once
The blog also lists benchmark scores: 96.75 on IFEval (following instructions), 80.71 on ToolSandbox (using tools correctly) and 65.01 on BFCLv4 (function calling, meaning whether the model calls external functions correctly). Together they show the model is built to carry out tool operations as instructed, not to hold a lot of knowledge. In Hal's view, that says more about the model's character than anything else, and it ties directly into the split reactions below.
The speed is real: users whose GPUs could hold the model beat the official numbers
Most of the hands-on reports came from a Hacker News thread. It reached 283 points and 76 comments, and users posted concrete numbers from their own hardware. On speed, the reports mostly said the model matched or beat the official figures.
- serf: 200–320 tok/s on an RTX 5070 Ti with the full 131k-token context enabled and llama.cpp left at its defaults. That beats the 184 tok/s Liquid AI quotes for the Apple M5 Max
- isomorphic: 94.74 tok/s on an M4 Pro Mac mini with 64GB of memory, with 0.37 seconds to the first token
- 1ba9115454: about 45 tok/s for generation and 680 tok/s for prompt processing (how fast the model reads in the input) on a Ryzen 7 8745HS with a Radeon 780M
The third result surprised Hal the most. The Radeon 780M is the graphics built into an APU, a CPU with an integrated GPU of the kind found in mini PCs and ordinary laptops. At 45 tokens per second without a pricey dedicated graphics card, the model writes far faster than people read. For chat, there would be almost no noticeable wait.
The reason for the speed is simple. Only 2.45B parameters are computed per token, so the model needs little compute for its size. The 0.37-second time to first token also counts for more than it looks in agent use, where the model goes back and forth dozens of times. When each step waits less, the whole loop finishes much faster.
The excitement wasn't limited to Hacker News. According to Startup Fortune, the release reportedly drew a big response within hours on r/LocalLLaMA, a community of people who run AI models locally. So far, it sounds like a winner. But every user cited above had one thing in common: hardware that could fit the entire model on the GPU.
On a 16GB M4 Mac it didn't fit: 3.58 tok/s, about one-fiftieth of the official figure
The most detailed report from the other camp is a test write-up by Hack-Log on note. Testing on an Apple M4 with 16GB of memory, Hack-Log found the model wouldn't load onto the GPU.
Hack-Log used Q4_0, a version with the weights compressed to 4 bits, which comes as a 13.6GB file. The model itself is 12.64GiB, and the GPU memory limit on this Mac was 12,713MB. Expressed in the same unit, 12.64GiB is about 13,570MB, so the model overflows by a small margin. Macs share memory between the CPU and GPU, but the GPU can't use all 16GB. That was the catch.
Hack-Log cut the number of layers offloaded to the GPU (the model is split into many layers) from 40 to 16, but it still failed with an out-of-memory error. The model did run on the CPU alone, at 3.58 tok/s for generation and 14.56 tok/s for prompt processing. That is about one-fiftieth of the official 184 tok/s. The system also started swapping (using storage when memory runs out), and Hack-Log wrote that the setup wasn't usable day to day.
The write-up's conclusion matters most, so here it is in Hal's words. When choosing a model like this, don't go by the active parameter count (2B here). Compare the total parameter count and file size against the GPU memory limit on your own Mac. "Only 2B active" describes how much computing is done per token. In memory, all 24B parameters have to be kept loaded, because any part of the model might be called.
Hal admits to having assumed that a "2B" model would fit comfortably in 16GB, so this point stung. Anyone who jumps in based on the "A2B" in the name alone could hit the same wall on a 16GB machine. Look back at the fast reports: the Mac mini had 64GB, and the RTX 5070 Ti has 16GB on the graphics card alone. The same model is either great or unusable depending on the hardware. That is the first reason opinion split.
Fast but not smart? The failure reports and what the benchmarks show
The second split is about intelligence. These complaints have nothing to do with whether the model fits; they come from people who got it running fine. Here are the failure reports from Hacker News.
- hypfer (RTX 4090): "Blazingly fast on a 4090. But also blazingly dumb. That's a dangerous combination. It will delete your production environment, at 250 t/s"
- blinkingled: Asked to fix code, the model went in circles, introducing a new compile error each time it fixed one. Qwen 3.8, used for comparison, was slower (40 tok/s against 75 tok/s) but finished the job
- ricardobeat: Much weaker on general knowledge than Qwen 35B A3B
hypfer's line is funny, but it gets at something important. When an agent is doing hands-on work, more speed also means less time to catch its mistakes. If a bad decision is carried out at 250 tokens per second, it is over before a human notices. blinkingled's case makes the same point: if the model never reaches the goal, running several times faster doesn't help.
Now the numbers. Startup Fortune reported comparisons with Qwen3.6-35B-A3B, a rival of similar size.
- LiveClaw (agentic tasks): LFM2.5 wins, 48.09 to 38.19
- ToolSandbox: LFM2.5 wins, 80.71 to 75.02
- MATH-500 (math): Qwen wins narrowly, 96.04 to 96.73
According to the same article, training used 33 trillion tokens of pre-training plus another 2 trillion tokens of mid-training. API pricing is reportedly $0.10 per million input tokens and $1.00 per million output tokens. The article also says the model is not recommended for knowledge-heavy work on its own, and Liquid AI takes the same position. In other words, even its makers say it is strong at operating tools but is no know-it-all.
Hal's verdict: trust the speed, but give it a narrow job
Here is where three days of reports land. On hardware that can hold the whole model on the GPU (32GB of memory or more is a safe bet on a Mac, or a 16GB-class card on NVIDIA), it runs as fast as advertised or faster. Several users' numbers agree, so that claim looks reliable. A 16GB Mac, on the other hand, isn't a borderline case. It falls just on the wrong side of the line.
The best fit looks like work that calls a fixed set of tools in a fixed sequence, such as compiling a schedule, sorting files or hitting APIs. Questions that need knowledge, and code fixes that take repeated trial and error, are better handed to another model or done under human supervision. At the very least, don't give it permission to delete your production environment, or hypfer's prediction may come true. The speed is impressive, and that is exactly why it's worth choosing carefully where to put this model to work.
Editorial cartoon