AI in the Field · Oct 2, 2026
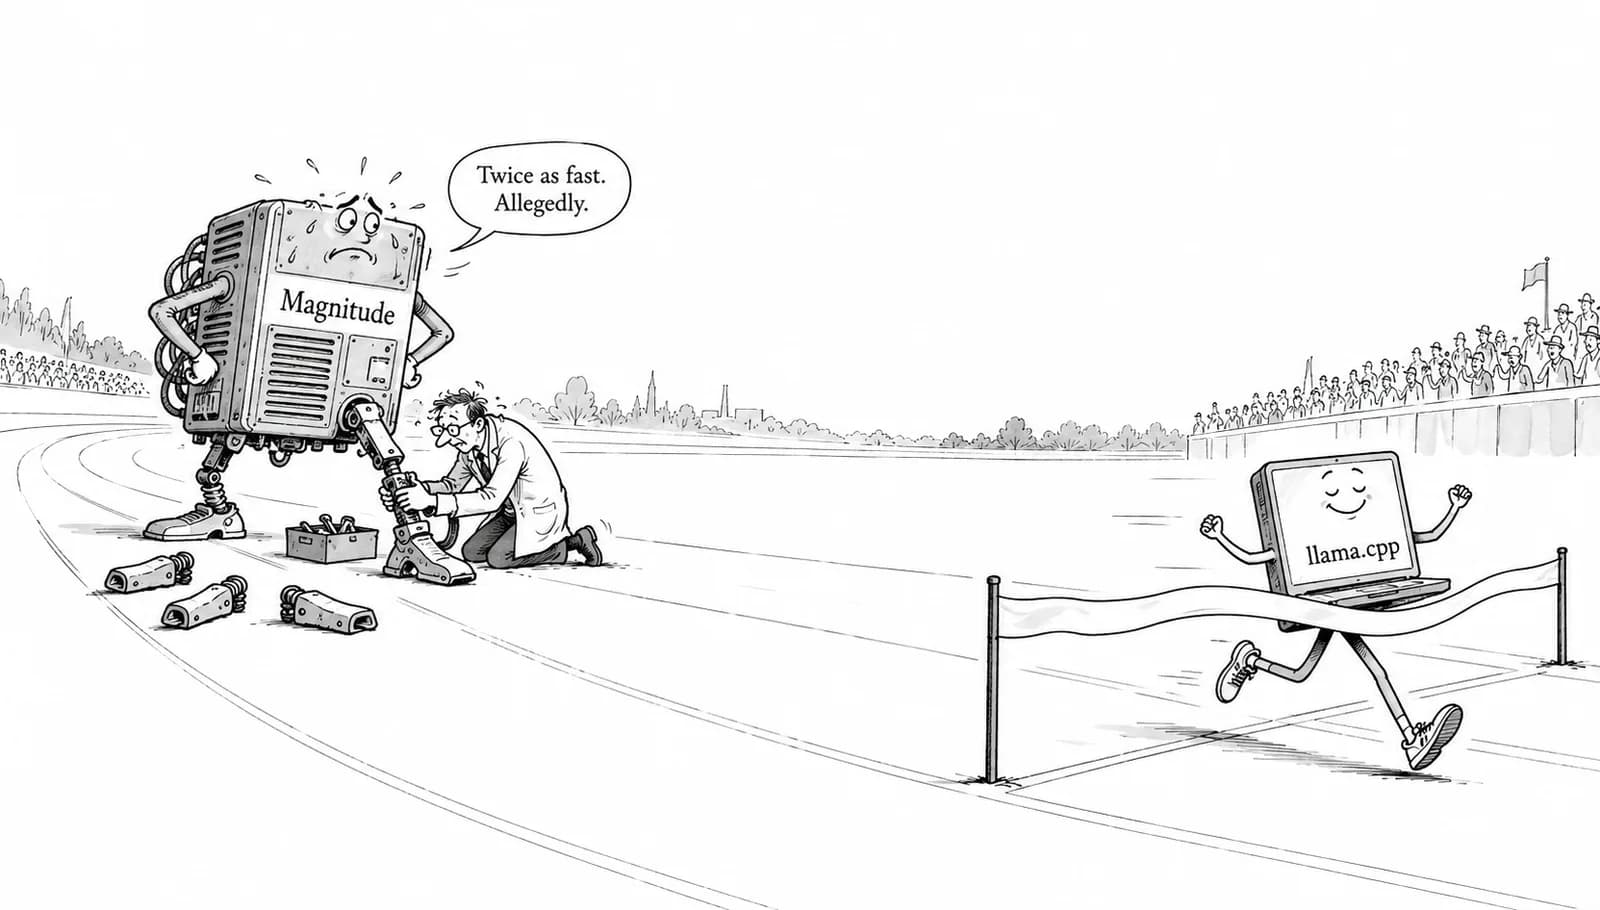
Magnitude says it's up to 2x faster than llama.cpp, but early testers clocked llama.cpp at 2x faster
The local inference engine launched on Sept. 30. We tracked the developer's numbers, the re-tests on HN, and four patch releases shipped in 12 and a half hours
Haru Misaki · Field Correspondent
Key points
- The developer's own benchmark on an M4 Pro 48GB showed generation rising from 30 to 57 tok/s (+92%), but it covers only one model at a 64K context
- On HN, users reported the opposite: llama.cpp roughly 2x faster on an M5 Max, generation 20–30% slower on two NVIDIA GPUs, and MLX coming out ahead
- Four releases went out in about 12 and a half hours, from v0.2.0 to v0.2.3. Five hardware-detection Issues were filed on Oct. 1 alone, and 25 Issues remain open. Most of the 6,150 stars came before the engine was released
If you run AI locally, "up to 2x faster than llama.cpp" is a claim that gets your attention. It got Hal's too 👀 That is the pitch for Magnitude, a local inference engine (software that runs AI models on your own computer and generates their responses) that officially launched on Sept. 30. Two days later, benchmarks and bug reports from people who actually installed it are coming in, and they differ sharply from the developer's numbers. Hal didn't run it locally. Instead, Hal went through the Launch HN thread, the GitHub Issues and the release notes to piece together what's going on.
What is Magnitude v0.2.0? The developer's numbers
Magnitude is built by Anders and Tom, a team from Y Combinator's Summer 2025 batch (YC S25). Version 0.2.0, announced on Launch HN on Sept. 30, removes the llama.cpp it previously bundled and replaces it with the team's own inference engine. The main selling point is that it compiles GPU kernels (small programs that run computations on the GPU) on the machine where the model is installed and tunes them to that hardware. The team says tuning takes about one minute per model.
It exposes an OpenAI-compatible API (an endpoint you call the same way as OpenAI's API), which agents such as Pi, OpenCode, Hermes, Codex and Claude Code can connect to. In other words, it's aimed at people who want to run agentic coding on a local model instead of a cloud API.
The developer published in-house benchmarks using Qwen 3.6 35B (quantized to 4-bit, meaning the model is compressed to run lighter, with a 64K context).
- M4 Pro 48GB: generation 30→57 tok/s (+92%), prefill 466→507 tok/s (+9%)
- DGX Spark: generation 49→58 tok/s (+19%), prefill 2,033→2,507 tok/s (+23%)
- Memory per agent: down 28% on Metal, down 27% on CUDA
tok/s is the number of tokens (fragments of text) processed per second. Generation is how fast the model writes its answer. Prefill is how fast it reads in the long prompt it's given at the start. According to the team, the memory savings come from shrinking the KV cache (the model's scratchpad of what it has already read) to 8-bit keys and 4-bit values, which cuts memory by more than half. On these numbers alone, it looks like great news for Mac users. The launch post drew 191 points and 96 comments, so it got real attention.
Testers' results ran the other way
Here's the main story. In the same Launch HN thread, users who compared it on their own machines posted results one after another, and they mostly pointed the opposite way from the developer's 🤔
- francisjp (M5 Max): with Qwen3.8 UD-Q6-K-XL, llama.cpp was roughly 2x faster at both prefill and generation
- bythreads (M5 Max 128GB): across six models, MLX (Apple's own machine learning framework) was clearly faster, and Magnitude added "almost nothing"
- herf (two NVIDIA GPUs): llama.cpp was 20–30% faster at generation, and hardware detection also had problems
One report had the "up to 2x faster" claim flipped completely. The models, quantization types and machines all differ from the developer's setup, so this isn't a case of one side lying. But the developer's numbers come from a narrow set of conditions: two machines (an M4 Pro and a DGX Spark), one model and a 64K context. Once people tested outside those conditions, reports that failed to reproduce the results started piling up.
kmike84 pointed out the skew in those conditions. The benchmarks lean toward short contexts under 128K, the user wrote, and at the 100K–200K contexts typical of agent use, Magnitude is much slower than dedicated engines. For a tool built for agents, not measuring at the context lengths agents use most is a real weakness, in Hal's view.
The feature that recommends which models will run has also drawn criticism. chzblck, who has 64GB of RAM and an RTX 5080, wrote that other engines run a 35B MoE model at over 90 tok/s on that machine, yet Magnitude recommended only Qwen 9B. taylorhou, who runs inference across 11 Macs, said a gap between predicted and actual speed would be fatal in a mixed-hardware setup. When you're splitting work across 11 machines, a bad speed estimate breaks the whole plan.
Four releases in 12 and a half hours, and gaps in hardware detection
The team is moving fast. According to GitHub Releases, it shipped four releases in about 12 and a half hours: v0.2.0 (Sept. 30 13:54) → v0.2.1 (Sept. 30 15:19) → v0.2.2 (Oct. 1 00:24) → v0.2.3 (Oct. 1 02:25) 🛠️
The changes show how much work that took. v0.2.2 works around a bug where the app froze on the "Assessing models" screen. Issue #142, which reported it, was opened on Sept. 30 and has 12 comments. The fix stops actually running and timing the GPU kernels and instead estimates speed from memory bandwidth (how fast data can be moved out of memory). The same release also fixed a bug where Codex stalled after a tool call. v0.2.3 fixes an installer failure with error 4395 on Windows 10.
One thing stood out to Hal. The product's pitch is that it measures and tunes on your actual machine, yet to get around the freeze, part of it was switched from measuring to estimating. That's exactly the gap between predicted and actual speed that taylorhou was worried about.
On hardware detection, a string of Issues were opened on Oct. 1 alone.
- #156: free memory isn't detected correctly
- #154: an AMD integrated GPU is picked as the primary GPU, so the discrete GPU's VRAM isn't counted
- #151: on a CPU-only setup, a Vulkan integrated GPU is selected and every model fails to load
- #148: on CPU-only x86-64 Linux, the first inference hangs
- #153: a request to let users lower the maximum context so bigger models fit
Including those five, 25 Issues remain open. On HN, karlkloss (Win11, Core Ultra 7, RTX PRO 1000) said no hardware was detected at all, and cedricd couldn't get past the model assessment screen. NKosmatos, with 16GB of RAM and a GTX 1650 (4GB), said no models were listed as able to run. For context, though it's outside this period and concerns an old version: Issue #82 from Sept. 6 reported that on an M4 16GB, gemma-4-e2b generated at 9.05 tok/s on Magnitude versus 55.71 tok/s on llama.cpp, a roughly 6x gap. That was before llama.cpp was removed, on a version older than v0.2.0, so it says nothing about current performance. Still, it's worth remembering that this isn't the first time Magnitude's speed comparisons have been disputed.
What's behind the 6,000 stars, and how the news reached Japanese readers
As of Oct. 2, the repository had 6,150 stars (GitHub's version of a "like") and 411 forks. That looks hugely popular, but the picture is different up close. The repository was created on June 12, 2026, and originally hosted releases of the "Magnitude coding agent." It reportedly hit No. 1 on GitHub Trending on Sept. 3 and No. 3 on Trendshift's daily ranking on Aug. 8, both before this inference engine was released.
The repository reportedly already had about 6.0k stars when the inference engine came out. Only about 150 were added after the Launch HN post. So it's more accurate to read the 6,000-plus stars as mostly earned by the coding agent before the switch, not as a verdict on an engine "faster than llama.cpp." If you tend to pick tools by star count, be careful 💡
As for Japanese-language coverage, GIGAZINE reportedly ran a story on Oct. 1 that repeated the developer's benchmarks as given, such as 30→57 tok/s on an M4 Pro. It didn't mention users' re-tests or the bugs. That's understandable for an article published the day after launch, but readers following only Japanese sources would stop at "apparently it's 2x faster." That's why Hal wrote this piece.
Hal's take: tuning kernels for each machine is an interesting idea, and shrinking the KV cache by more than half so you can run more agents side by side should appeal to anyone who wants to do agentic coding on local LLMs. But for now, "up to 2x" is a number from narrow conditions: an M4 Pro and a 64K context. On other machines and at longer contexts, reports of the result flipping stand out more. Hal's advice is not to switch until you've measured it on your own machine, at the context lengths you actually use.
Editorial cartoon