AI in the Field · Nov 10, 2026
Huge AI model on a PC with no GPU? A 3-day viral hit, but nobody besides the author has reproduced it yet
llama-modchip, a modified build by an individual developer, scored 475 points on HN. Almost all the results from people testing it on their own machines are for the 30B model, and we found no report of anyone other than the author running the 284B model
Haru Misaki · Field Correspondent
Key points
- The author says the 284B model was cut from 76.87GiB to 56.56GiB by quantizing it to an average of 1.71 bits, and it generated 9.06–10.74 tok/s on a 64GB PC with no GPU (up to 14.7 with extra speed-ups)
- The issue-tracker results we checked in detail (#9, #14 and #22) all used either a 30B model or an unquantized model, and there is no record yet of anyone other than the author reproducing the 284B result
- Other users say generation is no faster than standard llama.cpp, that the build crashes on older CPUs, that other software can't load its files, and that quality doesn't hold up at 1.7 bits
A DeepSeek model with 284B total parameters, running on an ordinary PC with no GPU and 64GB of memory. That is the claim behind "llama-modchip," a modified build made by an individual developer, and it collected 475 points within three days on Hacker News, the forum popular with engineers. Haru went through the repository, the forum thread and the issue tracker. Almost all the results people have posted from their own machines are for a smaller 30B model, and we found no record of anyone other than the author running the 284B model.
For Japanese companies: For most companies, this doesn't matter right now. IT staff at companies that want to use AI without sending sensitive data outside can check the repository's issue tracker this week to see whether anyone other than the author has run the 284B model. It is not yet a reason to rethink Copilot or ChatGPT Enterprise contracts.
What's the fuss about? Squeezing a model into a box it shouldn't fit
First, the author's claims. The project comes from synchopate, an individual GitHub account. It modifies llama.cpp, the go-to software for running AI models on a local PC, and pairs it with very aggressive quantization (rounding off the numbers inside the model so the file gets smaller). The target is DeepSeek-V4-Flash. The model has 284B parameters in total, but it only uses 13B of them for each response.
According to the author's README, even the smallest version from Unsloth, a well-known provider of quantized models, is 76.87GiB, too big for a 64GB PC. The author says they shrank the model to an average of 1.71bpw (bits per weight, an extremely compressed state) and got it down to 56.56GiB. With the context window raised to 256K, peak memory use was 57.61GiB. The author writes that the model fit in memory without swapping, which is when the system moves data out to slower storage because it has run out of memory.
The author's machine has a Ryzen 9 9955HX, 64GB of DDR5 memory and no GPU. On the same hardware, the unmodified software ran out of memory, swapped and generated 5.91 tok/s (tokens per second). The modified build reached 9.06–10.74 tok/s, and 11.5–14.7 tok/s with speculative decoding, a speed-up where a small model drafts the answer and the large model only checks it. The author also says prompt processing rose 77%, from 25.0 to 44.36 tok/s, after optimizations for the CPU's newer AVX-512 instructions. The repository was created on October 29 and has already reached v2.4.0. As of November 10, it had 781 stars and 41 forks.
The "it runs on my machine" reports from the forum and the issue tracker
Interest took off after someone other than the author posted it to Hacker News on November 8. The post rose near the top with 475 points and 204 comments. Some commenters reported results from their own hardware. One said it ran "steadily at 12–14 tok/s" on a low-power laptop (about 15W) with a Ryzen 7 5700U and 64GB of DDR4. Another said an M5 with 128GiB generated around 30 tok/s and processed prompts at about 400 tok/s.
This is the most important part of the story: neither commenter said which model they tested. We also checked the GitHub issue tracker, where users posted one result after another on November 8–9. In #9, a Ryzen 7 8745H with 96GB generated 19.48 tok/s, and 23.38 tok/s with speculative decoding (686 milliseconds to first response). In #14, a dual Xeon E5-2670 machine more than 10 years old reached 10.69 tok/s, and 11.47 tok/s with speculative decoding (2,014 milliseconds to first response). More than 10 tok/s from an old server is certainly a fun number.
A closer look shows that both #9 and #14 used NVIDIA's Nemotron-3.5-Lightning-30B. That is the 30B model, not the 284B model behind the headlines. The author has been adding reports like these to a results table. Other entries report 44.97 tok/s on Graviton3 (Amazon's cloud CPU), 31.22 on an EPYC 7402P and 20.78 tok/s on a Ryzen 9 9950X, but they don't name the model.
In another report (#22), a user connected the coding tool Pi to a local server. It first failed with a 403 error, meaning the connection was refused because the destination wasn't on an allowlist. The author fixed it on November 9, the same day as the report, and the user wrote that "startup took quite a while, but text generation went smoothly." The quick fix is a good sign. But this user also ran the regular, unquantized model, and the example settings in the author's reply were for the 30B model. The author's reply suggests the hardware was a Ryzen 7 5700U. The author says coding performance numbers will come later.
"Is it actually faster?" Skeptics, and reports of the build not running
Not every HN comment was praise. One user questioned whether "this AI-written repository actually does anything" and tested it on their own Ryzen 7945HX. They found that only prompt processing got faster, and generation speed was the same as standard llama.cpp. Another user pointed out that the file sizes in the README don't match Unsloth's original files, and went as far as calling the project AI-generated slop. Several people also complained that the README was hard to read and looked AI-written.
Some users couldn't get it to run at all. One said the prebuilt binary stopped with "Illegal instruction (core dumped)" on a Haswell-generation Xeon (from around 2013), meaning the program tried to use an instruction that CPU doesn't support, and that there were no instructions for building it from source. Files in the project's own quantization format, Fractal-64, also fail to load in unmodified llama.cpp, Ollama or LM Studio, which report "unknown tensor type 40." In other words, the files only work in this modified build. There is also no GPU compute support yet.
There are also strong concerns about answer quality. One person said the model is "barely usable at 1.75bpw," and another said a model this size needs about 150GB of memory to run properly. Cutting the numbers down to 1.7 bits makes the file smaller, but how much of the model's intelligence survives is a separate question. The harshest comment called the idea of running a heavily quantized model at 20 tok/s as a replacement for a Claude subscription "delusional."
"No degradation" compared to what? Media checks, and Haru's take
Ebenezer Don, a writer at the tech outlet CuriousLM, laid out the author's numbers and reported that no one besides the author has yet reproduced the 284B results. The article also notes that the author's claim of "no degradation" only compares the same 1.71-bit file before and after the modification, not against the full-precision model. It mentions that the README gives the unmodified build's generation speed as 5.91 tok/s while the model card says 6.41 tok/s, and that the numbers in the results table were submitted by the users themselves.
The news outlet AlphaSignal also reported the author's figures: compression from 76.87GiB to 56.56GiB, generation of 9–14.7 tok/s on a 64GB CPU-only machine, and peak memory use of 57.61–58.90GiB. It also reported that the files can't be loaded in standard Ollama or LM Studio and need the custom-built binary.
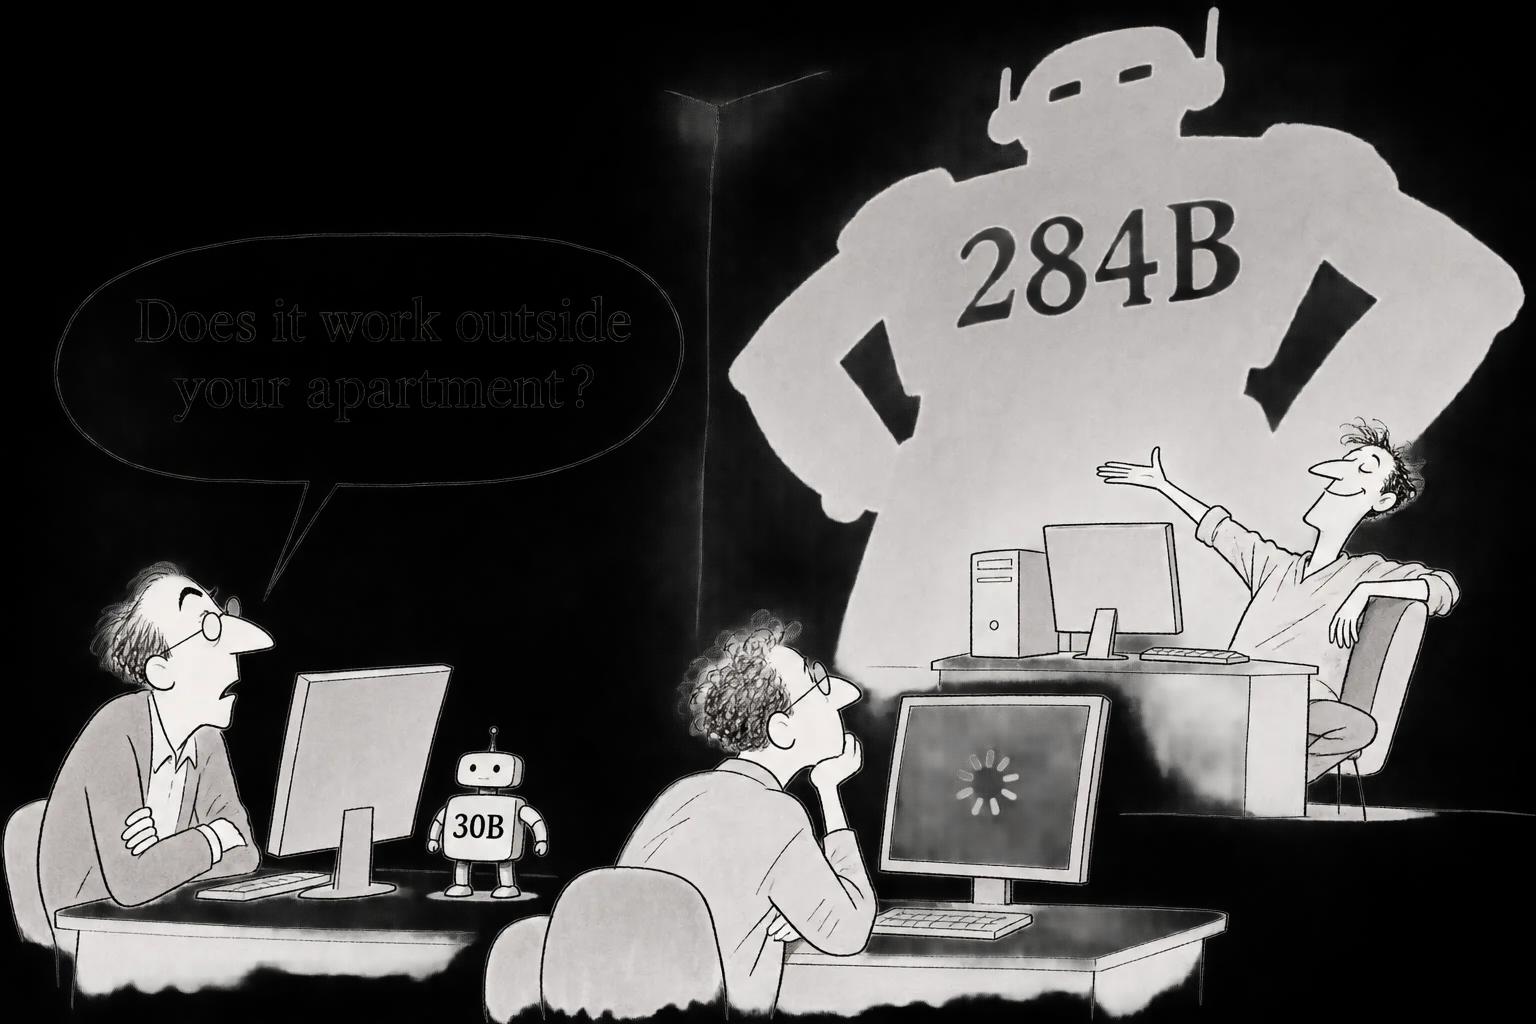
Here is what we could not verify. The fast numbers posted on HN (12–14 tok/s and around 30 tok/s) don't say which model was tested. The issue-tracker reports we checked in detail, #9, #14 and #22, all used either a 30B model or an unquantized model. The other numbers in the results table don't name a model. So for now, the claim that "284B ran at around 10 tok/s on a 64GB PC" rests on the author's measurements alone. We also found no side-by-side comparison of answer quality against the full-precision model.
Haru's take: getting a 30B model past 10 tok/s on an old server or a 15W laptop is fun to play with on its own, and it's exciting to watch the issue tracker grow into a shared lab notebook. But the headline claim that "284B runs without a GPU" is still only the author's word. Haru would first check whether the 30B model gives useful answers for your own needs, and wait for someone to reproduce the 284B result and compare its quality. It's also worth checking first whether your PC's CPU supports the newer instructions.
Editorial cartoon
Sources
- https://github.com/synchopate/llama-modchip
- https://news.ycombinator.com/item?id=50411961
- https://github.com/synchopate/llama-modchip/issues/9
- https://github.com/synchopate/llama-modchip/issues/22
- https://curiouslm.com/blog/llama-modchip-deepseek-v4-flash-64gb-cpu
- https://alphasignal.ai/news/llama-modchip-squeezes-deepseek-v4-flash-s-284b-model-into-64-gib-without-a-gpu