Rules & Policy · Oct 31, 2026
Four major AI labs reportedly unite behind a single opt-out signal for AI training, but rollout timelines vary
OpenAI, Google, Microsoft and Anthropic will reportedly standardize on "__usage_ai-training" in robots.txt. Sites could refuse training separately from answer grounding, but compliance ranges from already in place to sometime in 2027
Koji Yamamoto · Economics Analyst
Key points
- The four companies will reportedly standardize on "__usage_ai-training" as the robots.txt signal for opting out of AI training. It would be the first time major labs have adopted a common opt-out method
- Sites would reportedly no longer need to list each company's crawler names one by one, and they could separately refuse "use for training" and "use as grounding for answers"
- Timelines for honoring the signal vary, from companies that already support it to those that will start sometime in 2027. Until then, sites will need to keep their current company-by-company entries
OpenAI, Google, Microsoft and Anthropic will reportedly standardize on a single robots.txt signal, "__usage_ai-training," that websites can use to opt out of AI training, according to Unite.ai and FourWeekMBA. OpenAI reportedly has a page titled "Helping websites express AI training preferences," but its contents have not been verified. This article is based on media reports and could not be confirmed through primary sources.
If the reports are accurate, this would be the first time major frontier labs have adopted a common method for opting out of training. However, the companies reportedly differ widely on when they will actually start honoring the signal, ranging from some that already support it to others that will not do so until sometime in 2027.
What changes: from per-company entries to a single signal
Until now, sites that did not want their content used for training had to list, one by one in robots.txt, the crawler or user-agent names each company had chosen, such as OpenAI's GPTBot, Google's Google-Extended and Anthropic's ClaudeBot. Every new crawler meant another entry, and any company whose crawler name a site did not know would slip through.
According to the reports, "__usage_ai-training" is a signal that specifies a type of use rather than a particular company. A single line would tell every company that has pledged to honor the signal not to use the content for training. That would greatly reduce the burden on smaller sites and on news organizations that lack the resources to keep track of a growing number of crawlers.
Refusing "training" separately from "grounding answers"
The reported change with the biggest practical impact is that use for training could be handled separately from use as grounding for answers in search or agentic search.
Under the current company-by-company approach, blocking a crawler outright risked also removing a site from search results and from the sources cited in answers. That made it hard for sites to choose "don't use us for training, but do show us as a source in AI answers." Separating the signal by type of use would reportedly allow sites to refuse training while still permitting use as grounding. With AI answers increasingly becoming a gateway for traffic, this is the arrangement many publishers have been asking for.
The reports do not make clear how broadly "use as grounding" would be defined, or whether summaries and lengthy quotations would fall within it.
Staggered start dates leave a gap for now
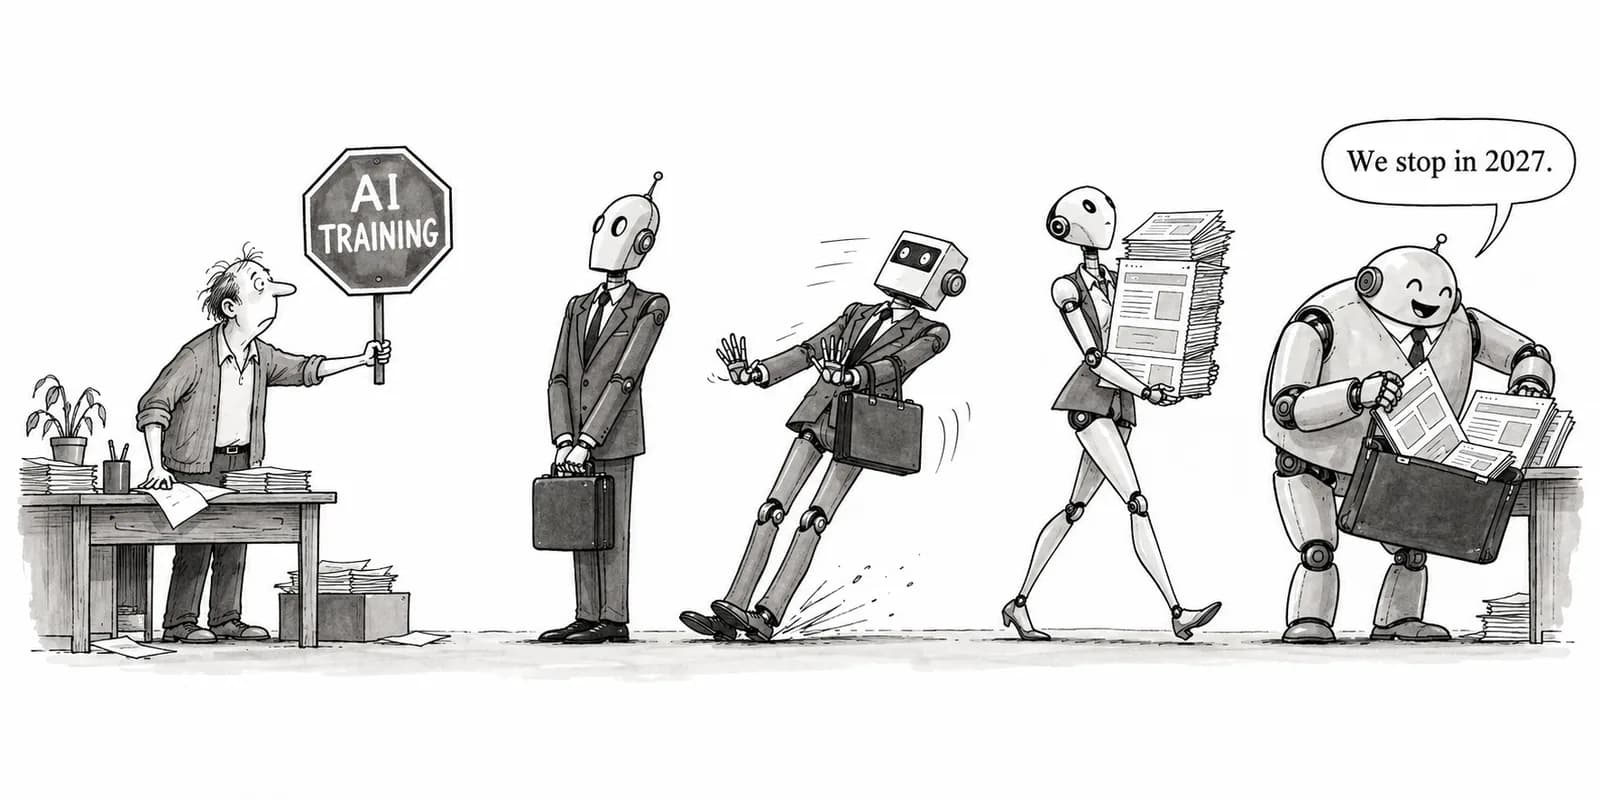
Some companies are reportedly already reading the signal, while others will not start honoring it until sometime in 2027. In the meantime, adding the shared signal alone will not stop training by companies that have yet to support it. For the time being, sites will need to keep their existing per-company crawler entries alongside "__usage_ai-training."
Robots.txt has also always been an unenforceable convention. Even with the four companies aligned, it has no effect on companies that do not participate or on crawlers that misrepresent their identity. The reports name the four companies, but they do not say whether Meta, xAI, Chinese labs or others will follow.
What remains unconfirmed
The following points have not been confirmed through primary sources: the exact syntax of the signal and how the distinction between "training" and "grounding" would be expressed; which of the four companies will comply and from when; in what forum the signal was agreed; and whether it would also apply to data already collected and used for training. Until the text of OpenAI's page and explanations from Google, Microsoft and Anthropic are published, the details described here remain at the level of media reports.
Even so, the direction is clear. The way sites opt out of training is shifting from company-specific rules to an industry-wide shared signal. The open question is when, and how fully, it will actually be honored.
Editorial cartoon